Blog
Guides to getting structured data out of documents in a form you can check: the method, the schema for each document type, and the numbers that come back.
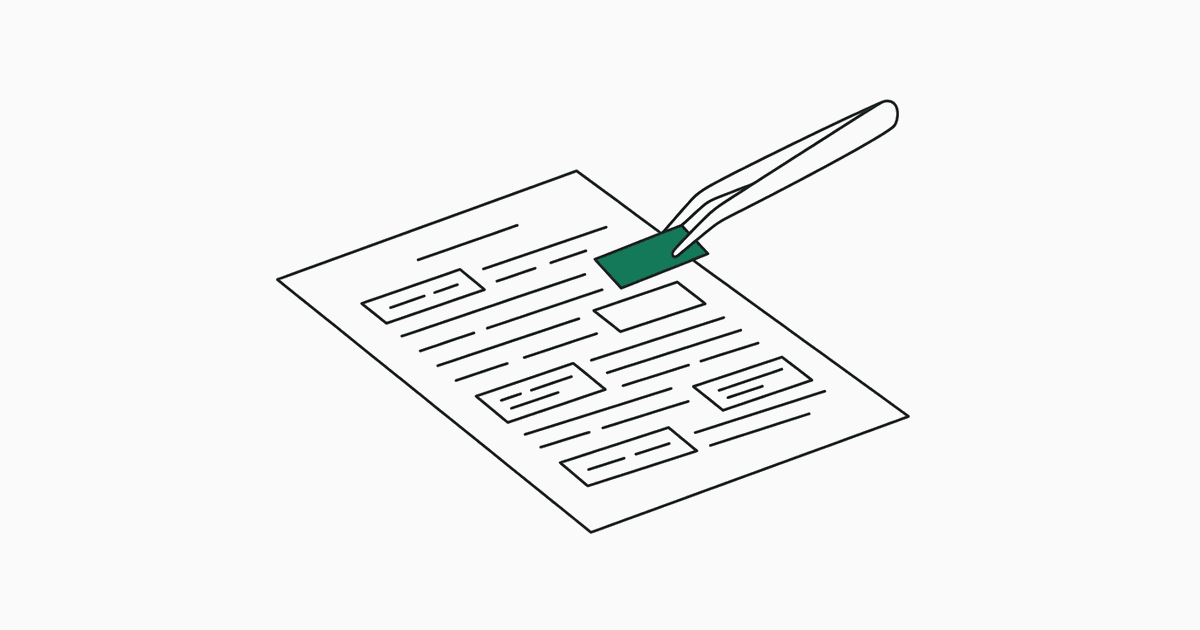
PDF data extraction without generation: choosing spans instead of writing JSON
Most PDF extractors ask an LLM to write JSON. jextract asks a model to choose a span that already exists on the page. Here is how that works and what it changes.
 , 6 min read
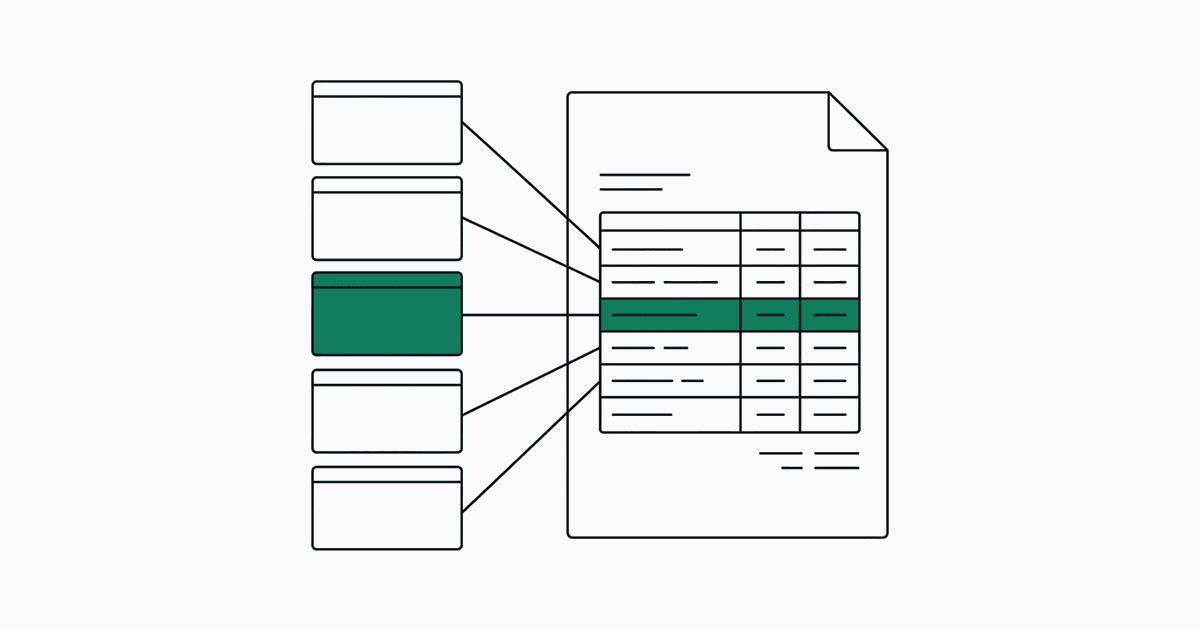
How to write a taxonomy for invoice extraction
A taxonomy is the list of fields you want from a document. This guide covers field types, descriptions, hints and enums, with a working invoice example.
 , 5 min read
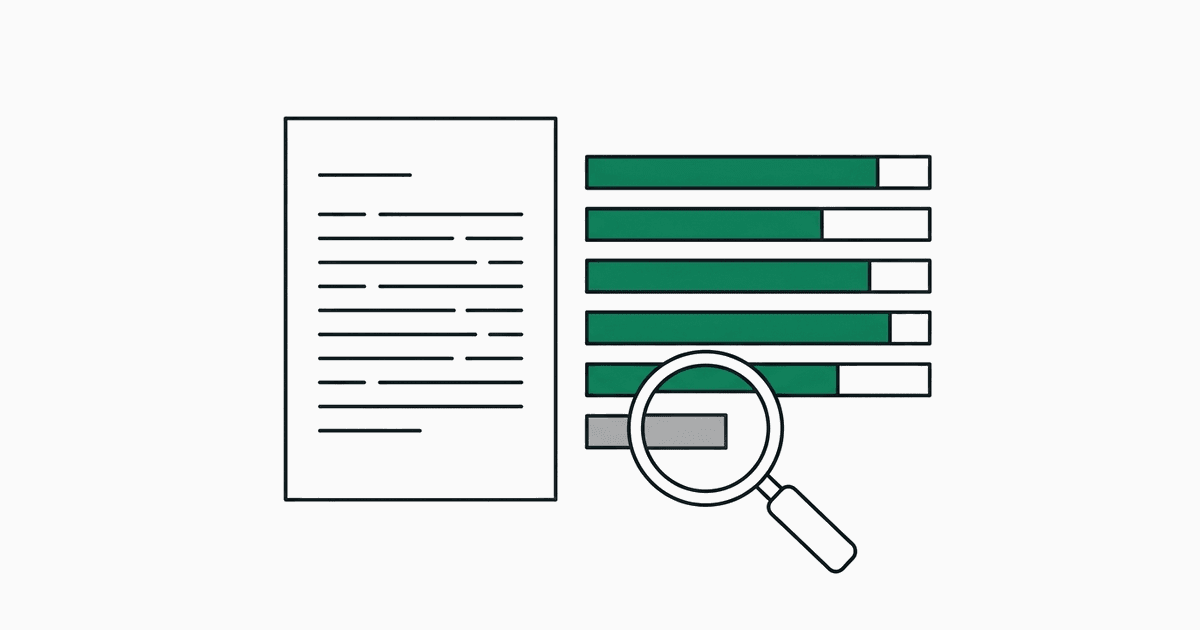
What a confidence score means in document extraction
A confidence of 0.94 should mean something you can act on. How jextract computes confidence from probabilities, what low-confidence and absent mean, and how to use them.
 , 5 min read
Contract data extraction: pulling parties, dates and terms from agreements
Which contract fields extract cleanly, which do not, and how to set up a taxonomy for parties, dates, fees, notice periods and governing law.
 , 4 min read
Résumé parsing with a taxonomy: structured candidate data from PDFs
How to turn a résumé PDF into structured fields: contact details, current role, experience and expectations, with the cases that need a human look.
 , 4 min read
Purchase order extraction: PO numbers, parties, totals and delivery terms
A practical field list for purchase order extraction, how to keep buyer and supplier apart, and what to do about line items.
 , 4 min read
Extracting data from scanned PDFs: when to turn OCR on
Text PDFs and scanned PDFs behave differently. What OCR adds, what it costs in speed and accuracy, and how to tell which kind of file you have.
 , 4 min read
Why every extracted value should come with a bounding box
A bounding box turns an extracted value from a claim into something you can check. What the box is, how it is produced and how to use it in review.
 , 5 min read
Extracting fields from long documents: chunks, windows and parallel search
How a 40-page PDF is searched without stuffing it into one prompt: chunking by layout, windows of about 22k tokens, and a locate step that runs in parallel.
 , 5 min read
PDF extraction API: from curl to structured JSON
A working guide to the jextract API: one multipart request, preset or custom taxonomies, streaming or plain JSON, and what every part of the response means.